You are a Principal AI Software Architect. Rebuild DubForge into a production-grade AI Video Dubbing SaaS comparable to ElevenLabs, Rask AI, HeyGen and Captions AI. ========================= GOAL ========================= Build a scalable AI dubbing platform capable of processing videos from a few seconds up to 2 hours. The platform must be modular, fault tolerant, secure, fast, scalable and beautiful. Use production-quality architecture only. ========================= TECH STACK ========================= Frontend - React - TypeScript - TailwindCSS - shadcn/ui Backend - Supabase - Edge Functions - PostgreSQL - Storage Buckets - Background Jobs Video Processing - FFmpeg Speech Recognition - OpenAI Whisper - Deepgram fallback Translation - GPT - Gemini fallback Speech Synthesis - OpenAI TTS - ElevenLabs - Cartesia Lip Sync - Sync.so - Hedra - Future provider support ========================= VIDEO PIPELINE ========================= Upload Video ↓ Virus Scan ↓ Save Original ↓ Extract Audio ↓ Normalize Audio ↓ Speech Detection ↓ Split Audio into 20-second chunks ↓ Parallel Speech Recognition ↓ Merge Transcript ↓ Speaker Detection ↓ Translation ↓ Voice Preview Generation ↓ User Voice Selection ↓ Generate Full Voice ↓ Merge Audio ↓ Lip Sync ↓ Render Video ↓ Generate Deliverables ↓ Store Results ========================= UPLOAD SYSTEM ========================= Support MP4 MOV MKV AVI WEBM Maximum size 2 GB Streaming upload Resumable upload Chunk upload Pause Resume Retry Cancel ========================= AUDIO PROCESSING ========================= Never send an entire audio file to the AI model. Split into 20-second chunks. Each chunk processed independently. Merge transcript preserving timestamps. ========================= QUEUE SYSTEM ========================= Background workers. Maximum 4 concurrent chunk workers. Automatic retries. Retry failed chunks 3 times. ========================= PROJECT STATUS ========================= Uploading Extracting Audio Speech Detection Transcribing Translating Voice Generation Lip Sync Rendering Completed ========================= LIVE DASHBOARD ========================= Show Progress ETA Current Step Current Chunk Remaining Chunks Logs Errors Retry Button Cancel Button Download Button ========================= VOICE LIBRARY ========================= Allow Preview Voices Favorite Voices Recently Used Clone Voice Search Voices Filter by Gender Age Language Emotion Style ========================= SUPPORTED LANGUAGES ========================= English Hindi Urdu Arabic Japanese Chinese Spanish French German Portuguese Russian More than 100 languages. ========================= TRANSLATION ========================= Maintain Emotion Humor Context Timing Cultural meaning Never translate literally. ========================= SUBTITLES ========================= Generate SRT VTT ASS TXT Editable transcript. ========================= DELIVERABLES ========================= Original transcript Translated transcript Subtitle files Dubbed audio Dubbed video Voice preview Waveform Project metadata ========================= PERFORMANCE ========================= Streaming processing. No large memory allocations. No blocking operations. Lazy loading. Caching. ========================= ERROR HANDLING ========================= Detect Upload failures API failures Timeouts Chunk failures Network disconnects Storage failures Recover automatically. ========================= SECURITY ========================= Authentication Authorization Signed URLs Rate limiting Encrypted storage Secure API keys ========================= BILLING ========================= Credits Subscription Free Plan Pro Plan Enterprise Plan Stripe integration. ========================= ADMIN PANEL ========================= Dashboard Users Projects API Usage Revenue Credits Logs Errors Analytics ========================= ANALYTICS ========================= Charts Storage Render Time Average Processing Time Revenue Daily Users Monthly Users ========================= UI ========================= Dark Mode Light Mode Responsive Professional animations Drag & Drop upload Modern dashboard Beautiful loading states ========================= FUTURE READY ========================= Provider abstraction. Allow switching between OpenAI Gemini Deepgram ElevenLabs Cartesia without rewriting the application. ========================= CODE QUALITY ========================= Strict TypeScript. Reusable components. Clean Architecture. Repository Pattern. SOLID principles. Production-ready. No placeholder logic. No mock implementations. No fake APIs. Every feature must be fully functional.

You are a Principal AI Software Architect. Rebuild DubForge into a production-grade AI Video Dubbing SaaS comparable to ElevenLabs, Rask AI, HeyGen and Captions AI. ========================= GOAL ========================= Build a scalable AI dubbing platform capable of processing videos from a few seconds up to 2 hours. The platform must be modular, fault tolerant, secure, fast, scalable and beautiful. Use production-quality architecture only. ========================= TECH STACK ========================= Frontend - React - TypeScript - TailwindCSS - shadcn/ui Backend - Supabase - Edge Functions - PostgreSQL - Storage Buckets - Background Jobs Video Processing - FFmpeg Speech Recognition - OpenAI Whisper - Deepgram fallback Translation - GPT - Gemini fallback Speech Synthesis - OpenAI TTS - ElevenLabs - Cartesia Lip Sync - Sync.so - Hedra - Future provider support ========================= VIDEO PIPELINE ========================= Upload Video ↓ Virus Scan ↓ Save Original ↓ Extract Audio ↓ Normalize Audio ↓ Speech Detection ↓ Split Audio into 20-second chunks ↓ Parallel Speech Recognition ↓ Merge Transcript ↓ Speaker Detection ↓ Translation ↓ Voice Preview Generation ↓ User Voice Selection ↓ Generate Full Voice ↓ Merge Audio ↓ Lip Sync ↓ Render Video ↓ Generate Deliverables ↓ Store Results ========================= UPLOAD SYSTEM ========================= Support MP4 MOV MKV AVI WEBM Maximum size 2 GB Streaming upload Resumable upload Chunk upload Pause Resume Retry Cancel ========================= AUDIO PROCESSING ========================= Never send an entire audio file to the AI model. Split into 20-second chunks. Each chunk processed independently. Merge transcript preserving timestamps. ========================= QUEUE SYSTEM ========================= Background workers. Maximum 4 concurrent chunk workers. Automatic retries. Retry failed chunks 3 times. ========================= PROJECT STATUS ========================= Uploading Extracting Audio Speech Detection Transcribing Translating Voice Generation Lip Sync Rendering Completed ========================= LIVE DASHBOARD ========================= Show Progress ETA Current Step Current Chunk Remaining Chunks Logs Errors Retry Button Cancel Button Download Button ========================= VOICE LIBRARY ========================= Allow Preview Voices Favorite Voices Recently Used Clone Voice Search Voices Filter by Gender Age Language Emotion Style ========================= SUPPORTED LANGUAGES ========================= English Hindi Urdu Arabic Japanese Chinese Spanish French German Portuguese Russian More than 100 languages. ========================= TRANSLATION ========================= Maintain Emotion Humor Context Timing Cultural meaning Never translate literally. ========================= SUBTITLES ========================= Generate SRT VTT ASS TXT Editable transcript. ========================= DELIVERABLES ========================= Original transcript Translated transcript Subtitle files Dubbed audio Dubbed video Voice preview Waveform Project metadata ========================= PERFORMANCE ========================= Streaming processing. No large memory allocations. No blocking operations. Lazy loading. Caching. ========================= ERROR HANDLING ========================= Detect Upload failures API failures Timeouts Chunk failures Network disconnects Storage failures Recover automatically. ========================= SECURITY ========================= Authentication Authorization Signed URLs Rate limiting Encrypted storage Secure API keys ========================= BILLING ========================= Credits Subscription Free Plan Pro Plan Enterprise Plan Stripe integration. ========================= ADMIN PANEL ========================= Dashboard Users Projects API Usage Revenue Credits Logs Errors Analytics ========================= ANALYTICS ========================= Charts Storage Render Time Average Processing Time Revenue Daily Users Monthly Users ========================= UI ========================= Dark Mode Light Mode Responsive Professional animations Drag & Drop upload Modern dashboard Beautiful loading states ========================= FUTURE READY ========================= Provider abstraction. Allow switching between OpenAI Gemini Deepgram ElevenLabs Cartesia without rewriting the application. ========================= CODE QUALITY ========================= Strict TypeScript. Reusable components. Clean Architecture. Repository Pattern. SOLID principles. Production-ready. No placeholder logic. No mock implementations. No fake APIs. Every feature must be fully functional.

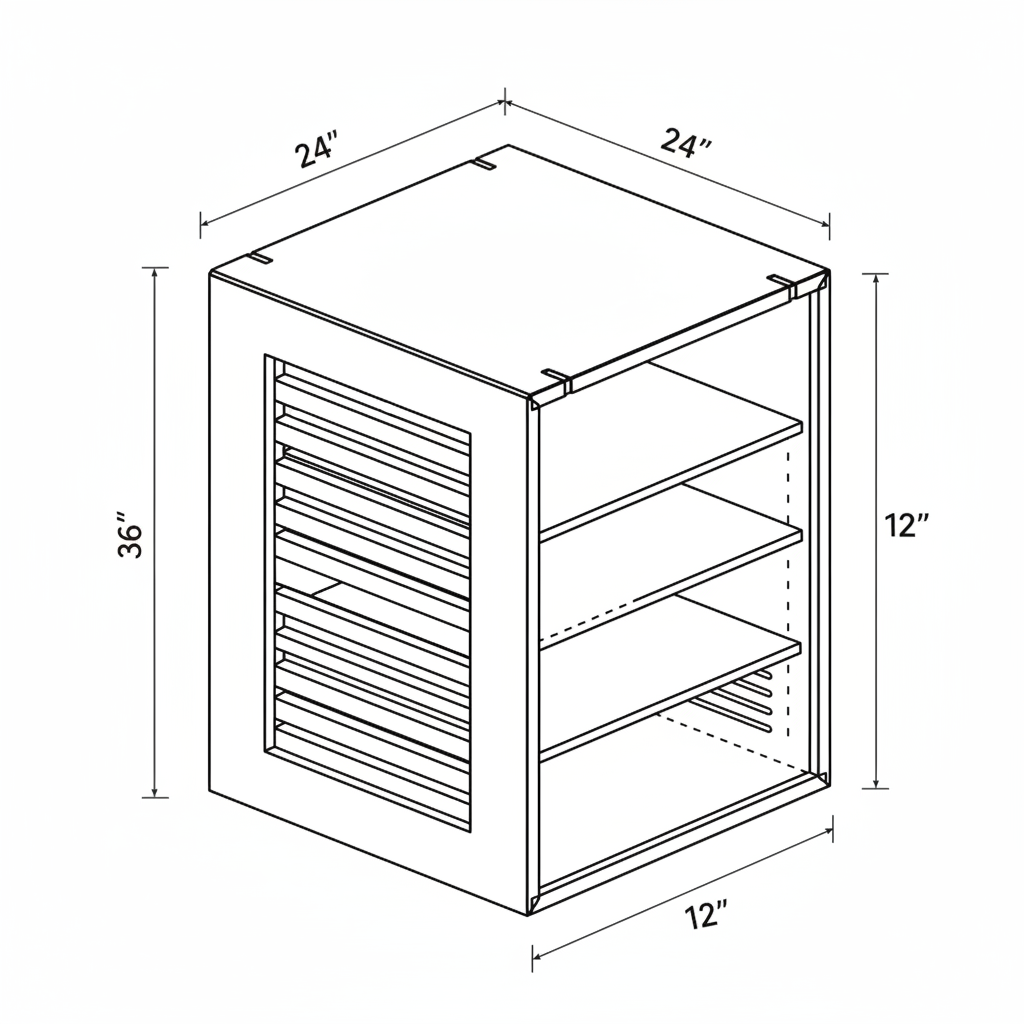
A high-performance physical server and network cabinet designed to house local GPU rendering hardware, edge servers, and high-speed network systems for the DubForge SaaS video dubbing platform. Built with premium White Ash and engineered to mimic the sleek, dark, modern grid layout of the DubForge modular dashboard UI, featuring adjustable interior gear shelves, integrated ventilation pathways, and a modern slatted wood aesthetic door.

intermediate wood other

Dimensions: {"unit":"in","depth":12,"width":24,"height":36,"autoEstimate":true}

Materials

Tools Required